Identity & privacy
The Internet Should Be More Like a Liquor Store
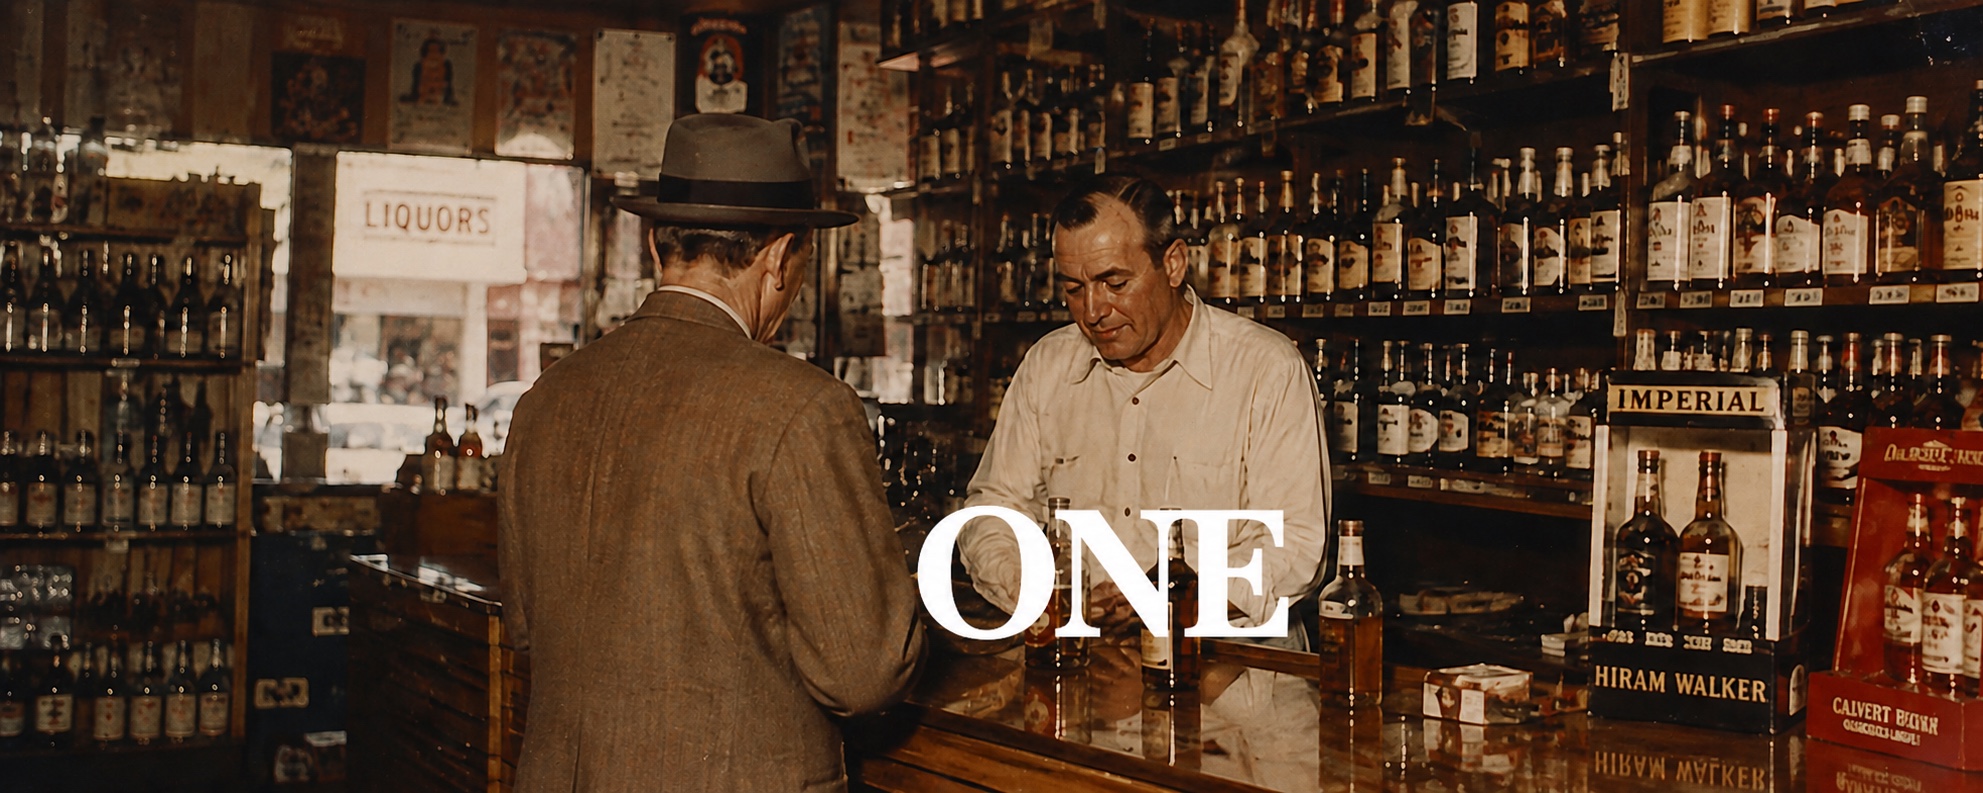
Since I first started the weekend project that has gradually evolved into ONE in early 2024, I’ve been fixated on the idea that while the internet has revolutionized the way we interact with the world by reducing the effort and cost of so many tasks, it has also rendered a certain facet of everyday life much more difficult than in the physical world.
What once required getting in a car, driving into town, and entering a storefront can now happen from anywhere on earth, in seconds. But the moment an individual needs to prove some aspect of their identity online, the process becomes strangely more annoying and invasive than it is in person.
There are reasons for this, some of them even good, and these are not new challenges. But as governments and institutions around the world require more applications to verify their users’ ages, two competing problems are becoming increasingly difficult to ignore.
The Friction Problem
Proving your age online is cumbersome. A typical verification flow asks you to pull out your government ID, photograph it, upload it, take a selfie, or alternately complete a liveness check. This might be tolerable once, but identity verification on the internet is fragmented, so the next application requiring proof of your age doesn’t know you’ve already been verified, and so you do it again. And again.
For users, this is an undue burden. For businesses and application owners, it’s a significant barrier between a new user and their product. And what feels like the obvious solution, to verify someone once and allow them to reuse that verification, creates an even bigger problem.
The Privacy Problem
Reusable identity requires data persistence. If an identity provider deletes your documents after verifying your age, you’ll eventually need to upload them again. If it retains them, it creates a database containing some of the most sensitive information its users possess. Names, addresses, dates of birth, government identification numbers. Photographs of driver’s licenses. A honeypot sitting in the cloud, vulnerable to bad actors inside or outside the providing institution.
The more useful a reusable identity provider becomes, the more sensitive data it accumulates, and the more valuable a target it becomes.
So we end up with an uncomfortable tradeoff: make identity verification repeatable, or make it private.
The Liquor Store
At the beginning of what became ONE, I settled on a much simpler model for identity verification: buying something at a liquor store. You walk into the store anonymously. You browse without identifying yourself. Only when you bring a bottle to the counter does the clerk ask for your ID.
You reach out your hand and present it.
The clerk looks at the ID, looks at you, checks your birthdate, and gives you a nod. That’s it. Nobody asks to make a photocopy of your driver’s license. No account is created containing your name and address. No database exists containing a record that you were at that liquor store, on that day, buying that bottle. The store learns the one thing it needs to know: you’re old enough. And you’re on your way.
That image became the North Star for ONE. Online identity verification should work like reaching out your hand, briefly presenting your ID, and receiving that quick nod of approval. But making that interaction repeatable without creating a massive repository of sensitive user data required a different architecture.
Solving the Friction Problem
ONE is effectively a privacy-preserving identity provider. Built on top of the OAuth 2.0 Authorization Code flow, a user verifies their identity once, and after that initial onboarding, applications can request specific proofs about that user through a familiar consent screen.
For example, an application that needs to know whether you’re over 18 receives the necessary proof without seeing your name, address, date of birth, or any other sensitive data. With this approach, age verification can truly become one tap across the internet. But as you’ll remember, that’s only half the problem.
Solving the Privacy Problem
If everyone’s identity documents were simply stored in perpetuity for reuse, we would solve our first problem at the cost of making the second (and arguably most critical), the Privacy Problem, dramatically worse. So ONE was designed around a different constraint — even ONE should not be able to read the sensitive identity data it persists.
This constraint led to the core privacy-preserving identity primitive that ONE is built on: persistent, reusable identity data encrypted with a user-held key.
When identity documents are uploaded, they are encrypted using a master encryption key derived from the user’s passkey during authentication. The key is derived on the user’s device and never leaves it. This means the documents can persist and be reused for future verification without ONE possessing the secret required to decrypt them. And if ONE’s systems were ever compromised, an attacker likewise would be unable to decrypt sensitive persisted data in the absence of the user-held encryption key.
The same primitive addresses the two problems that otherwise pull against each other. Identity can be persistent enough to be frictionless, while preserving privacy to a degree where the identity provider itself does not need to be trusted with the underlying data.
In the physical world, we’ve been doing something remarkably similar for decades. You reach out your hand. You prove what needs to be proven. And then you put your ID back in your pocket.